Principal engineer building production AI agents. I write about running models on my own GPU, AI dev tools, and what I'm building.
Opinions here are my own and don't represent my employer.
Principal engineer building production AI agents. I write about running models on my own GPU, AI dev tools, and what I'm building.
Opinions here are my own and don't represent my employer.
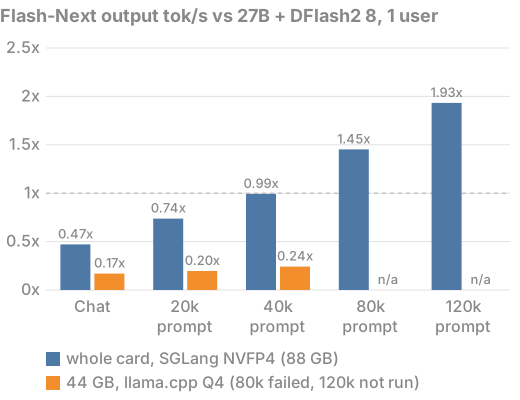
On one RTX PRO 6000, Qwen3.8-Flash-Next NVFP4 on SGLang beats Qwen3.8-27B NVFP4 without a drafter in every scenario I ran. Against the 27B with DFlash2 (8 draft tokens), the setup I run day to day, it is about half as fast at chat, ties at 40k, and wins only from 80k: 1.9x at 120k. It takes the whole card for that, 88 GB against 44 GB. Squeezed into 44 GB with llama.cpp, it runs at a fifth to a quarter of the 27B’s speed.
Whole card, output tok/s, median time to first token (TTFT) in parentheses, one run per config. Bold is the fastest.
| Scenario | 27B NVFP4, no drafter | 27B NVFP4 + DFlash2 8 | Flash-Next NVFP4, no drafter |
|---|---|---|---|
| Chat, 1 user | 72.0 (44 ms) | 178.0 (48 ms) | 83.9 (81 ms) |
| Chat, 4 users | 233.7 (183 ms) | 592.5 (73 ms) | 305.2 (168 ms) |
| 20k prompt, 1 user | 52.9 (2.33 s) | 98.4 (2.35 s) | 72.6 (1.69 s) |
| 20k prompt, 4 users | 94.7 (5.77 s) | 137.5 (5.73 s) | 134.2 (4.35 s) |
| 40k prompt, 1 user | 39.1 (5.53 s) | 58.7 (5.57 s) | 58.3 (3.41 s) |
| 80k prompt, 1 user | 22.5 (14.7 s) | 28.5 (14.8 s) | 41.4 (6.98 s) |
| 120k prompt, 1 user | 14.2 (27.6 s) | 16.5 (27.8 s) | 31.9 (10.6 s) |
| GPU memory after load | 43.8 GB (0.41) | 43.8 GB (0.41) | 87.7 GB (0.88) |
The 27B numbers are the runs from the spec-decode post, not rerun.
At the 27B’s 44 GB budget (llama.cpp, Q4 GGUF, experts of 30 of 48 layers in host RAM):
| Scenario | 27B NVFP4 + DFlash2 8 | Flash-Next UD-Q4_K_XL, 44.3 GB |
|---|---|---|
| Chat, 1 user | 178.0 (48 ms) | 30.2 (1.11 s) |
| Chat, 4 users | 592.5 (73 ms) | 37.2 (4.40 s) |
| 20k prompt, 1 user | 98.4 (2.35 s) | 19.3 (9.81 s) |
| 20k prompt, 4 users | 137.5 (5.73 s) | 21.6 (15.9 s) |
| 40k prompt, 1 user | 58.7 (5.57 s) | 14.2 (19.7 s) |
| 80k prompt, 1 user | 28.5 (14.8 s) | failed |
This run is partial: 80k failed (see caveats) and 120k didn’t run.
--ple-offload-embedding) is rejected together with SGLang’s weight offload flags (--cpu-offload-gb, --offload-group-size), and KTransformers’ expert offload doesn’t support the model yet (ktransformers#2179, open on 2026-10-29). With llama.cpp, the experts in host RAM cost 3x in decode (32–33 ms per token) and about 4x in prefill (756 vs 2,835 prompt tok/s at 20k).I’m keeping the 27B with DFlash2 as the daily driver. Most of my requests are short to medium prompts, and the model that wins only past 40k costs the other half of the card.
Hardware: same machine as the NVFP4 vs FP8 post. RTX PRO 6000 Blackwell 96 GB at a 400 W power limit, PCIe Gen 4 x16, Ryzen 9 7950X, 250 GiB DDR5, Ubuntu 24.04.2, driver 580.178.04, rootless Docker. Full list in hardware.md.
Model: Qwen/Qwen3.8-Flash-Next, 125B parameters with 6B active per token, plus a 51B n-gram embedding and a 4B MTP head. 48 layers: 36 Gated DeltaNet, 12 Qwen Sparse Attention.
Flash-Next, whole card:
lmsysorg/sglang:nightly-dev-cu13-20261029-c10e0e17, with PYTORCH_CUDA_ALLOC_CONF=expandable_segments:True and SGLANG_OPT_MAMBA_SKIP_DECODE_LOCK=1.RadixArk/Qwen3.8-Flash-Next-NVFP4 @ 7b719225.python3 -m sglang.launch_server --model-path <checkpoint>
--mem-fraction-static 0.88 --max-running-requests 4 --max-mamba-cache-size 12
--context-length 262144 --dtype bfloat16 --quantization modelopt_fp4 --tp 1
--reasoning-parser qwen3 --tool-call-parser qwen3_coder
--cuda-graph-backend-prefill disabled
--ple-offload-embedding --mamba-ssm-dtype bfloat16
--mamba-radix-cache-strategy extra_buffer_lazy --mamba-track-interval 64
--chunked-prefill-size 2048 --page-size 64 --kv-cache-dtype fp8_e4m3 --sleep-on-idlePrefill chunks of 2048 and no prefill CUDA graph: with 4096-token chunks, the first 20k-token prefill ran out of GPU memory at --mem-fraction-static 0.92–0.96.
Flash-Next, 44 GB:
ghcr.io/ggml-org/llama.cpp@sha256:0283744a (b11977).unsloth/Qwen3.8-Flash-Next-GGUF @ 766911a6, UD-Q4_K_XL (103.7 GiB).--n-cpu-moe 30 sets the GPU memory: 44.3 GB after load, 44.5 GB peak. Host RAM 47–64 GiB.llama-server -m <UD-Q4_K_XL shard 1>
-ngl 999 -ot per_layer_token_embd=CPU --n-cpu-moe 30 -fit off
-c 153600 -kvu --parallel 4 -fa on --jinja -b 4096 -ub 4096 -t 16 -lm none27B: RadixArk/Qwen3.8-27B-NVFP4 @ 319f741c, with and without z-lab/Qwen3.8-27B-DFlash2 (8 draft tokens), on lmsysorg/sglang:nightly-dev-cu13-20261010-961bcf48, --mem-fraction-static 0.41, context 153,600, 64 GiB HiCache in host RAM. Flags in the spec-decode post.
Serving: python3 -m sglang.benchmark.serving --warmup-requests 2 --seed 1, reasoning_effort=medium. Backend sglang-oai-chat with --flush-cache on SGLang; vllm-chat on llama.cpp, with cache_prompt: false on every request because llama.cpp has no cache flush endpoint.
random dataset, which repeats one ShareGPT prompt to length. It’s the same input for every config, but it isn’t a real long document.--mem-fraction-static 0.92–0.96 and ran out of GPU memory on the first 20k prefill. I didn’t try them at 0.88. Stock SGLang also caps the Flash-Next draft block at 4 tokens. A drafter would raise the whole-card chat numbers; it can’t fix the memory.parallel (4/20) and parallel_multiple (10/20). The responses really do make one call where two are needed, but BFCL’s Qwen/Qwen3-32B-FC handler builds its own prompt instead of using the model’s chat template, so I don’t trust that as a model comparison. The scores and every response are in the repo.ignore_eos), so this measures speed only.results/fn-nospec/ (whole card) and results/fn-gguf-q4/ (44 GB): bench-serving.jsonl (one line per scenario, server args included), server.log, resources.json (GPU and host memory, startup time), and bfcl/ with every model response.On one RTX PRO 6000 with SGLang, DFlash2 with 8 draft tokens is the fastest drafter for stock Qwen3.8-27B NVFP4 in every scenario I ran, from short chat to a 120k-token prompt. It beats the model’s own MTP head at 3 and 7 steps, DFlash2 with 4 draft tokens, and RadixArk’s DSpark. Tool calling (BFCL) doesn’t move.
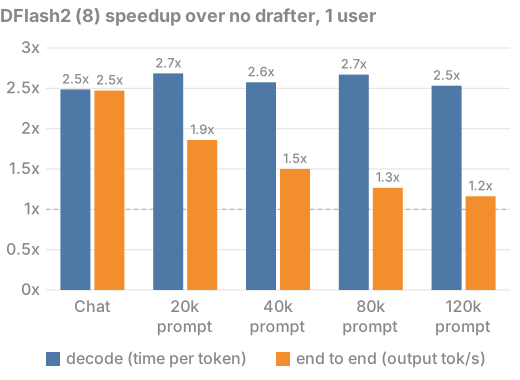
The end-to-end gain drops from 2.5x on chat to 1.16x at 120k. That’s prefill, not the drafter: time per output token stays about 2.5x faster at every length.
Output tok/s, one run per config. Bold is the fastest.
| Scenario | No drafter | MTP 3 | MTP 7 | DFlash2 4 | DFlash2 8 | DSpark |
|---|---|---|---|---|---|---|
| Chat, 1 user | 72.0 | 143.8 | 143.0 | 143.3 | 178.0 | 148.1 |
| Chat, 4 users | 233.7 | 522.0 | 506.5 | 489.5 | 592.5 | 503.8 |
| 20k prompt, 1 user | 52.9 | 85.1 | 84.3 | 84.9 | 98.4 | 88.8 |
| 20k prompt, 4 users | 94.7 | 129.9 | 127.9 | 131.5 | 137.5 | 131.2 |
| 40k prompt, 1 user | 39.1 | 52.9 | 55.0 | 54.5 | 58.7 | 56.9 |
| 80k prompt, 1 user | 22.5 | 26.4 | 26.8 | 27.1 | 28.5 | 27.5 |
| 120k prompt, 1 user | 14.2 | 15.3 | 15.4 | 15.9 | 16.5 | 15.9 |
| BFCL subset, correct of 205 | 171 | 173 | 173 | 176 | 176 | 171 |
Mean accept length (tokens per verify step, 1 user):
| Config | Chat | 20k | 40k | 80k | 120k |
|---|---|---|---|---|---|
| MTP 3 | 2.80 | 2.87 | 2.74 | 2.90 | 2.84 |
| MTP 7 | 3.36 | 3.41 | 3.65 | 3.79 | 3.55 |
| DFlash2 4 | 2.81 | 2.79 | 2.76 | 2.70 | 2.66 |
| DFlash2 8 | 3.43 | 3.54 | 3.28 | 3.43 | 3.46 |
| DSpark | 2.84 | 2.95 | 3.07 | 2.88 | 2.70 |
DFlash2 with 8 draft tokens is what I run day to day, and nothing here changes that.
Same --mem-fraction-static 0.41 for every config. The draft model and verify buffers come out of the same budget:
| Config | KV pool (tokens) | Mamba slots |
|---|---|---|
| No drafter | 318,592 | 117 |
| MTP 3 | 276,224 | 39 |
| MTP 7 | 264,256 | 24 |
| DFlash2 4 | 244,160 | 44 |
| DFlash2 8 | 236,864 | 28 |
| DSpark | 241,216 | 28 |
DFlash2 8 gives up 26% of the KV pool and 76% of the mamba slots (max_total_num_tokens and mamba_cache_size from each server.log). With 4 running requests and a 153,600-token context that’s still enough for every scenario above. I haven’t measured what it costs in multi-turn prefix cache hits.
The DFlash2 card reports 4.10 on MT-Bench with 7 draft tokens (H200, xhigh reasoning). I get 3.43 on ShareGPT at medium. So I reran DFlash2 8 with thinking off and with temperature 0:
| Scenario | DFlash2 8 | Thinking off | Temperature 0 |
|---|---|---|---|
| Chat, 1 user, out tok/s | 178.0 | 184.7 | 177.2 |
| Chat, 4 users, out tok/s | 592.5 | 566.0 | 593.2 |
| 20k prompt, 1 user, out tok/s | 98.4 | 101.2 | 98.5 |
| 20k prompt, 4 users, out tok/s | 137.5 | 140.0 | 138.5 |
| Chat, 1 user, accept length | 3.43 | 3.57 | 3.41 |
Neither one closes the gap. The prompts (ShareGPT vs MT-Bench) and the hardware differ, so the card’s number isn’t a target I should expect to hit.
Hardware: same machine as the NVFP4 vs FP8 post. RTX PRO 6000 Blackwell 96 GB at a 400 W power limit, Ryzen 9 7950X, 250 GiB DDR5, Ubuntu 24.04.2, driver 580.178.04, rootless Docker. Full list in hardware.md.
Serving stack:
lmsysorg/sglang:nightly-dev-cu13-20261010-961bcf48 for every config (it has both DFLASH and DSPARK).RadixArk/Qwen3.8-27B-NVFP4 @ 319f741c.z-lab/Qwen3.8-27B-DFlash2 @ 50307d4c, RadixArk/Qwen3.8-27B-DSpark @ b9a5dbdf (DSpark v2). MTP uses the head built into the target checkpoint.reasoning_effort=medium.Shared flags, the same as the first post:
python3 -m sglang.launch_server --model-path <checkpoint>
  --mem-fraction-static 0.41 --max-running-requests 4 --context-length 153600
  --dtype auto --attention-backend flashinfer
  --reasoning-parser qwen3 --tool-call-parser qwen3_coder
  --mamba-full-memory-ratio 0.9 --mamba-ssm-dtype bfloat16
  --mamba-radix-cache-strategy extra_buffer_lazy
  --chunked-prefill-size 2048 --page-size 64
  --enable-hierarchical-cache --hicache-size 64 --hicache-write-policy write_through
  --kv-cache-dtype fp8_e4m3 --schedule-policy lpm --enable-session-radix-cache
  --sleep-on-idle --trust-remote-code
Then the speculative flags, appended after the shared ones:
| Config | Flags |
|---|---|
| MTP 3 | --speculative-algorithm EAGLE --speculative-num-steps 3 --speculative-eagle-topk 1 --speculative-num-draft-tokens 4 |
| MTP 7 | same with --speculative-num-steps 7 --speculative-num-draft-tokens 8 |
| DFlash2 4 | --speculative-algorithm DFLASH --speculative-draft-model-path <DFlash2> --speculative-num-draft-tokens 4 |
| DFlash2 8 | same with --speculative-num-draft-tokens 8 |
| DSpark | --speculative-algorithm DSPARK --speculative-draft-model-path <DSpark> --speculative-draft-model-quantization unquant --speculative-draft-attention-backend flashinfer --speculative-dspark-block-size 7 --speculative-num-steps 1 --speculative-eagle-topk 1 |
Serving: python3 -m sglang.benchmark.serving --backend sglang-oai-chat --flush-cache --warmup-requests 2 --seed 1.
BFCL: bfcl-eval 2026.3.23, the Qwen/Qwen3-32B-FC handler, the same fixed 205-case subset as the first post (case ids).
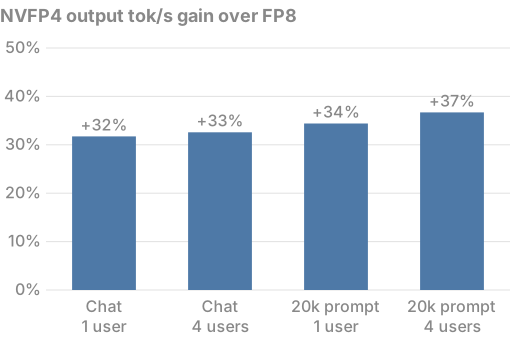
--mamba-radix-cache-strategy extra_buffer, --mamba-full-memory-ratio 11.93 and 32k prefill chunks. With those it might do better than here.ignore_eos), so this measures speed only.unsloth/Qwen3.8-27B-NVFP4, and I stopped at 120k, so this doesn’t contradict them.run.sh reruns every config, about two hours.results/<label>/ per config: bench-serving.jsonl (one line per scenario, full server args included), server.log, and bfcl/ with every model response.On one RTX PRO 6000 with SGLang and DFlash2 speculative decoding, NVFP4 is 32–37% faster than FP8 for stock Qwen3.8-27B, on short chat and on 20k-token prompts. BFCL tool calling stays within noise (174 vs 167 of 205).
Stock Qwen3.8-27B: Qwen/Qwen3.8-27B-FP8 vs RadixArk/Qwen3.8-27B-NVFP4.
| Scenario | FP8 | NVFP4 | Δ |
|---|---|---|---|
| Chat, 1 user, out tok/s | 133.8 | 176.3 | +32% |
| Chat, 4 users, out tok/s | 449.9 | 596.5 | +33% |
| 20k prompt, 1 user, out tok/s | 73.3 | 98.5 | +34% |
| 20k prompt, 4 users, out tok/s | 104.1 | 142.3 | +37% |
| 20k prompt, 1 user, TTFT p50 | 3.20 s | 2.34 s | −27% |
| 20k prompt, 4 users, TTFT p50 | 8.48 s | 5.78 s | −32% |
| DFlash2 accept length, chat 1 user | 3.49 | 3.41 | −2% |
| BFCL subset, correct | 167/205 | 174/205 | +7 |
| BFCL mean latency per call | 1.22 s | 0.92 s | −25% |
irrelevance (12 → 18) and multi_turn_base (14 → 16), categories of 20 cases each.| Category | FP8 | NVFP4 |
|---|---|---|
| simple_python | 25/25 | 25/25 |
| multiple | 24/25 | 23/25 |
| parallel | 18/20 | 18/20 |
| parallel_multiple | 19/20 | 19/20 |
| live_simple | 18/20 | 18/20 |
| live_multiple | 20/25 | 19/25 |
| multi_turn_base | 14/20 | 16/20 |
| multi_turn_miss_param | 3/10 | 4/10 |
| irrelevance | 12/20 | 18/20 |
| live_irrelevance | 14/20 | 14/20 |
| Total | 167 | 174 |
Hardware and system:
nvidia-smi reports Gen 4 as this system’s maximum). Power limit 400 W, set at boot (default 600 W). Idle during runs, one config at a time.Serving stack:
lmsysorg/sglang:nightly-dev-cu13-20261010-961bcf48.Qwen/Qwen3.8-27B-FP8 @ 017b9c7a, RadixArk/Qwen3.8-27B-NVFP4 @ 319f741c.z-lab/Qwen3.8-27B-DFlash2), 8 draft tokens, for every run.--mem-fraction-static 0.50 for FP8, 0.41 for NVFP4, so both get about the same KV pool (240,512 vs 236,864 tokens, 28 mamba slots each).reasoning_effort=medium.Launch flags:
python3 -m sglang.launch_server --model-path <checkpoint>
  --mem-fraction-static <0.50|0.41> --max-running-requests 4 --context-length 153600
  --dtype auto --attention-backend flashinfer
  --reasoning-parser qwen3 --tool-call-parser qwen3_coder
  --speculative-algorithm DFLASH --speculative-draft-model-path <DFlash2>
  --speculative-num-draft-tokens 8
  --mamba-full-memory-ratio 0.9 --mamba-ssm-dtype bfloat16
  --mamba-radix-cache-strategy extra_buffer_lazy
  --chunked-prefill-size 2048 --page-size 64
  --enable-hierarchical-cache --hicache-size 64 --hicache-write-policy write_through
  --kv-cache-dtype fp8_e4m3 --schedule-policy lpm --enable-session-radix-cache
  --sleep-on-idle --trust-remote-code
Serving: python3 -m sglang.benchmark.serving --backend sglang-oai-chat --flush-cache --warmup-requests 2 --seed 1.
BFCL: bfcl-eval 2026.3.23, the Qwen/Qwen3-32B-FC handler, a fixed 205-case subset across 10 categories (case ids).
ignore_eos), so tok/s compares speed only, not how much each model thinks.unsloth/Qwen3.8-27B-NVFP4: 50.9 → 56.4 tok/s without MTP, 115.8 → 132.3 with MTP k=2, single stream (repo). The engine, checkpoint and speculative decoding all differ from mine, and I haven’t tested which of them explains the difference.run.sh there reruns both configs.results/<label>/bfcl/ in the same folder.