On one RTX PRO 6000, Qwen3.8-27B NVFP4 with DFlash2 (8 draft tokens) is about twice as fast as Qwen3.8-Flash-Next NVFP4 at chat (178.0 vs 83.9 tok/s, 1 user), measured 58.7 vs 58.3 tok/s at 40k (one run cannot resolve that gap), and uses half the GPU memory: 42.8 GiB against 85.6 GiB. Flash-Next leads only from 80k: 1.45x at 80k, 1.9x at 120k. That holds for 512-token answers, one user and one repeated prompt per length. On a llama.cpp GGUF at about the 27B’s memory (43.3 GiB), Flash-Next runs at 6–24% of that 27B’s speed (17% at chat with 1 user). Without a drafter, the 27B is slower than Flash-Next in every scenario I ran. These are end-to-end serving configurations (different checkpoints, engines and offload), not an architecture-only comparison.
Results
Whole card, output tok/s (total output tokens over the benchmark’s wall time across all requests, prefill included; not per-user speed), median time to first token (TTFT) in parentheses, one run per config. Bold is the fastest; where two cells are bold (40k, and 20k with 4 users) one run each can’t separate them (58.7 vs 58.3, 137.5 vs 134.2).
| Scenario | 27B NVFP4, no drafter | 27B NVFP4 + DFlash2 8 | Flash-Next NVFP4, no drafter |
|---|---|---|---|
| Chat, 1 user | 72.0 (44 ms) | 178.0 (48 ms) | 83.9 (81 ms) |
| Chat, 4 users | 233.7 (183 ms) | 592.5 (73 ms) | 305.2 (168 ms) |
| 20k prompt, 1 user | 52.9 (2.33 s) | 98.4 (2.35 s) | 72.6 (1.69 s) |
| 20k prompt, 4 users | 94.7 (5.77 s) | 137.5 (5.73 s) | 134.2 (4.35 s) |
| 40k prompt, 1 user | 39.1 (5.53 s) | 58.7 (5.57 s) | 58.3 (3.41 s) |
| 80k prompt, 1 user | 22.5 (14.7 s) | 28.5 (14.8 s) | 41.4 (6.98 s) |
| 120k prompt, 1 user | 14.2 (27.6 s) | 16.5 (27.8 s) | 31.9 (10.6 s) |
GPU memory after load (--mem-fraction-static) | not measured (0.41) | 42.8 GiB (0.41) | 85.6 GiB (0.88) |
The 27B numbers are the runs from the spec-decode post, not rerun. GPU memory is nvidia-smi MiB shown as GiB (MiB / 1024). The 27B no-drafter run has no resources.json, so that cell is not measured. The DFlash2 cell (43,849 MiB) comes from the resources.json of the same server config in the Swift vs stock data; Flash-Next is 87,663 MiB.
At about the 27B’s GPU memory (llama.cpp, Q4 GGUF, experts of 30 of 48 layers in host RAM):
| Scenario | 27B NVFP4 + DFlash2 8 | Flash-Next UD-Q4_K_XL, 43.3 GiB |
|---|---|---|
| Chat, 1 user | 178.0 (48 ms) | 30.2 (1.11 s) |
| Chat, 4 users | 592.5 (73 ms) | 37.2 (4.40 s) |
| 20k prompt, 1 user | 98.4 (2.35 s) | 19.3 (9.81 s) |
| 20k prompt, 4 users | 137.5 (5.73 s) | 21.6 (15.9 s) |
| 40k prompt, 1 user | 58.7 (5.57 s) | 14.2 (19.7 s) |
| 80k prompt, 1 user | 28.5 (14.8 s) | failed |
This run is partial: 80k failed (see caveats) and 120k didn’t run.
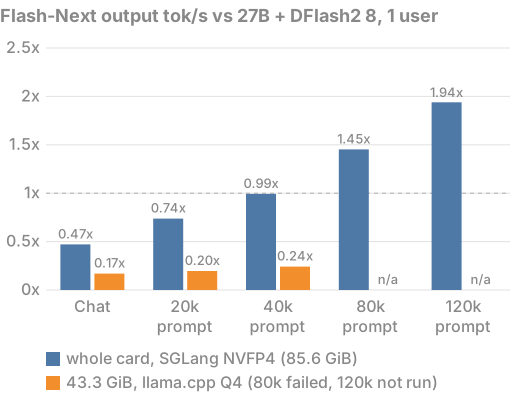
Takeaways
- Flash-Next has the lower long-prompt TTFT, the 27B the faster decode. At 1 user, time to first token (consistent with faster prefill; it also includes queueing and the first token) is 1.4x lower at 20k (1.69 vs 2.35 s), 2.1x at 80k (6.98 vs 14.8 s) and 2.6x at 120k (10.6 vs 27.8 s). At chat length it’s higher (81 vs 48 ms).
- Decode at 1 user is flat at 10.4–10.7 ms per output token. That beats the 27B without a drafter (13.8–16.5 ms) and loses to the 27B with DFlash2 (5.4–6.5 ms).
- Where it wins depends on the answer length. These requests are 512 output tokens, so the 40k near-equal rates and the 80k/120k lead are for that length only. From the medians, the 27B with DFlash2 catches up after about 1,600 output tokens at 80k and about 4,100 at 120k. That’s my estimate (TTFT difference over per-token difference), not a measurement.
- It needs the whole card. 85.6 GiB of GPU memory, against 42.8 GiB for the 27B with DFlash2, which leaves half the card free.
- Host RAM is about 70 GiB on top, mostly the 51B-parameter n-gram embedding table (~48 GiB in FP8), which SGLang keeps in pinned memory.
- I couldn’t get SGLang under about 43 GiB. The image rejects
--ple-offload-embeddingtogether with--cpu-offload-gband--offload-group-size. KTransformers’ expert offload doesn’t support the model yet (ktransformers#2179, open on 2026-10-29). - llama.cpp does fit in 43.3 GiB, with the experts in host RAM. At 1 user, decode costs 3x the whole-card run (32–33 ms per token) and TTFT at 20k is 5.8x (9.81 vs 1.69 s).
With these repeated prompts, 512-token answers and one user, Flash-Next leads past 40k, and it takes the whole card to do it.
Setup
Model: Qwen/Qwen3.8-Flash-Next, 125B parameters with 6B active per token, plus a 51B n-gram embedding and a 4B MTP head. 48 layers: 36 Gated DeltaNet, 12 Qwen Sparse Attention.
Flash-Next, whole card:
- Image:
lmsysorg/sglang:nightly-dev-cu13-20261029-c10e0e17, withPYTORCH_CUDA_ALLOC_CONF=expandable_segments:TrueandSGLANG_OPT_MAMBA_SKIP_DECODE_LOCK=1. - Checkpoint:
RadixArk/Qwen3.8-Flash-Next-NVFP4@7b719225. - No drafter. KV pool 611,520 tokens, 12 mamba slots.
python3 -m sglang.launch_server --model-path <checkpoint>
  --mem-fraction-static 0.88 --max-running-requests 4 --max-mamba-cache-size 12
  --context-length 262144 --dtype bfloat16 --quantization modelopt_fp4 --tp 1
  --reasoning-parser qwen3 --tool-call-parser qwen3_coder
  --cuda-graph-backend-prefill disabled
  --ple-offload-embedding --mamba-ssm-dtype bfloat16
  --mamba-radix-cache-strategy extra_buffer_lazy --mamba-track-interval 64
  --chunked-prefill-size 2048 --page-size 64 --kv-cache-dtype fp8_e4m3 --sleep-on-idle
Chunks of 2048 and no prefill CUDA graph came after a first attempt (native MTP, --mem-fraction-static 0.96, 4096-token chunks) ran out of GPU memory on the first 20k-token prefill. I didn’t test the two changes separately.
Flash-Next, llama.cpp:
- Image:
ghcr.io/ggml-org/llama.cpp@sha256:0283744a(b11977). - Checkpoint:
unsloth/Qwen3.8-Flash-Next-GGUF@766911a6,UD-Q4_K_XL(103.7 GiB). --n-cpu-moe 30sets the GPU memory: 43.3 GiB (44,311 MiB) after load, 43.4 GiB peak. Host RAM 47–64 GiB.
llama-server -m <UD-Q4_K_XL shard 1>
  -ngl 999 -ot per_layer_token_embd=CPU --n-cpu-moe 30 -fit off
  -c 153600 -kvu --parallel 4 -fa on --jinja -b 4096 -ub 4096 -t 16 -lm none
27B: stock RadixArk/Qwen3.8-27B-NVFP4 @ 319f741c, with and without z-lab/Qwen3.8-27B-DFlash2 (8 draft tokens), on lmsysorg/sglang:nightly-dev-cu13-20261010-961bcf48, --mem-fraction-static 0.41, context 153,600, 64 GiB HiCache in host RAM. Flags in the spec-decode post.
Serving: python3 -m sglang.benchmark.serving --warmup-requests 2 --seed 1, reasoning_effort=medium for the serving scenarios (BFCL uses the handler’s default effort, see caveats). Temperature 0, top-p 1. Output lengths are fixed with ignore_eos. Backend sglang-oai-chat with --flush-cache on SGLang; vllm-chat on llama.cpp, with cache_prompt: false on every request because llama.cpp has no cache flush endpoint.
- Chat: ShareGPT prompts, 1024 output tokens; 12 prompts at 1 user, 32 at 4 users.
- 20k prompt: SGLang
randomdataset (one ShareGPT prompt repeated to 20,000 tokens), 512 output tokens; 4 prompts at 1 user, 8 at 4 users. - 40k, 80k, 120k prompt: same dataset, 512 output tokens, 4 prompts at 1 user.
Caveats
- One run per config. The long scenarios have 4 prompts each, and 20k with 4 users has 8. One run does not resolve a difference of a few percent: 134.2 vs 137.5 at 20k with 4 users (2.4%) is a tie as far as these data go.
- The long prompts use SGLang’s
randomdataset, which repeats one ShareGPT prompt to length. It’s the same input for every config, but it isn’t a real long document. - The 27B and Flash-Next runs used SGLang nightlies 19 days apart (2026-10-10 and 2026-10-29), and Flash-Next has no HiCache. I didn’t rerun the 27B on the newer image.
- No drafter on Flash-Next. Native MTP loaded at
--mem-fraction-static0.96 and ran out of GPU memory on the first 20k prefill (chunk 4096). I didn’t try it at 0.88, and I didn’t run incoai/Qwen3.8-Flash-Next-DFlash2. Stock SGLang also caps the Flash-Next draft block at 4 tokens. A drafter might raise the whole-card chat numbers; I have no measurement either way. - No quality comparison. On the 205-case subset of BFCL V4 (Berkeley Function Calling Leaderboard) used in the earlier 27B posts, scored by automatic graders, this Flash-Next run got 136/205 vs 168–176 for the 27B NVFP4 runs, over half of the gap in
parallel(4/20 vs 18–19 for the 27B) andparallel_multiple(10/20 vs 18–19). None of the 16 failedparallelresponses has two tool calls: the model makes one call or answers in prose. But BFCL’sQwen/Qwen3-32B-FChandler builds its own prompt instead of using the model’s chat template, so I don’t trust that as a model comparison. BFCL ran at the handler’s default effort and temperature 0.001, notreasoning_effort=medium. The scores and every response are in the repo. - The llama.cpp run is partial. At 80k the unified KV pool (153,600 tokens) ran out because the first warmup request was still in slot 0 when the second started, and the client failed on a non-JSON stream chunk. Two 78k requests in a row on a fresh server worked. 120k didn’t run, and BFCL generated 181 of 205 responses but did not finish or score.
- 400 W power limit, not the default 600 W. Output lengths are fixed (
ignore_eos), so this measures speed only.
Raw data
- Scripts, configs and raw results: adcostanza/benchmarks. The 27B results are in the spec-decode folder.
- The scripts on
mainkeep changing. To rerun with the scripts as of this post, check out45d1fd2. results/fn-nospec/(whole card) andresults/fn-gguf-q4/(llama.cpp):bench-serving.jsonl(one line per scenario, server args included),server.log,resources.json(GPU and host memory, startup time), andbfcl/with the generated responses (all 205 forfn-nospec; 181 forfn-gguf-q4, unscored).
Test system
- GPU: NVIDIA RTX PRO 6000 Blackwell Workstation Edition, 96 GB, power limit 400 W (default 600 W). Nothing else on the GPU, one config at a time.
- PCIe: Gen 4 x16 (the card supports Gen 5;
nvidia-smireports Gen 4 as this system’s maximum). - CPU: AMD Ryzen 9 7950X, 16 cores, 32 threads.
- RAM: 250 GiB DDR5.
- OS: Ubuntu 24.04.2, kernel 6.8.0-147.
- NVIDIA: driver 580.178.04, CUDA 13.0.
- Containers: rootless Docker 28.0.4, NVIDIA Container Toolkit 1.18.1, GPU through CDI.
- Full list: hardware.md at the commit these runs used.